comet eval evaluates built-in tasks and local Skills. Define a custom task when your scenario needs fixed instructions, an environment, or validation scripts. This page explains how to configure the task, treatment, profile, and interaction mode.
This article is advanced custom content. If you just want to evaluate an existing Skill, there’s no need to read this article - just use
comet eval./your-skill —html is fine. This article assumes that you have already been able to run successfully
comet eval ./your-skill —collect。How do you read this page
Custom eval can be understood in three layers. In most scenarios, the Task is completed first, and then the Profile or Treatment is adjusted as needed.
If you only want to add stable acceptance conditions to the local Skill, it is preferred to declare inline tasks in
comet/eval.yaml of the Skill package, or use source to reference the tasks within the Skill package. Run --collect first, then --html. Only when it is necessary to expand the built-in harness of the Comet repository, is it necessary to create a task directory and register it to index.yaml. Profile, Treatment and auto_user can all be adjusted after the first version of the task runs smoothly.
Eval configuration structure
A complete eval is composed of three parts. Understanding their division of labor is the foundation of customization: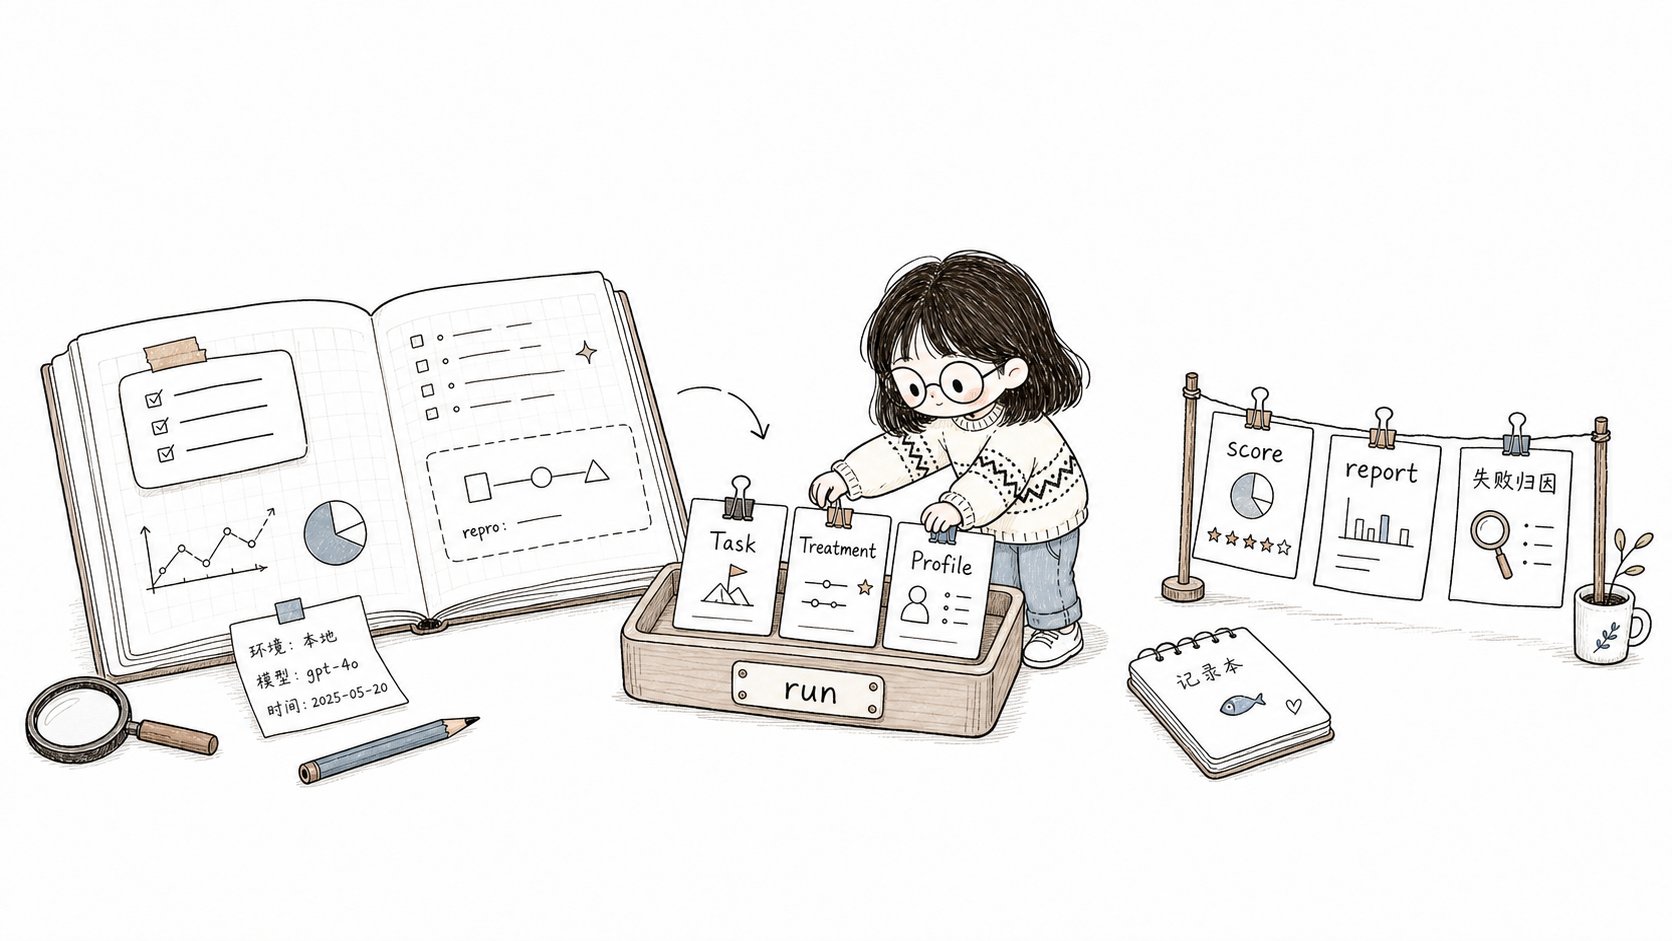
Task decides what to test, Treatment decides what to inject, and Profile and Rubric decide how to score
Let’s explain each one clearly below.
Define a Task
Each task is a directory underlocal/tasks/, containing four files:
local/tasks/my-task/
task.toml
instruction.md
environment/
Dockerfile
validation/
test_my_task.py
The Task directory convention comes from eval harness (
eval/), not your business repository. Expansion
Comet built-in harness in warehouse, custom task on eval/local/tasks/
And register to eval/local/tasks/index yaml; Ordinary Skill
There is no need to copy this directory structure. inline task or package-local task can be used.1. Write task.toml
task.toml is the core configuration of task, which is divided into four parts:
The key fields of [evaluation]
These fields directly determine the scoring results and are worth explaining separately:
2. Write instruction.md
This is a task instruction for the agent, supporting template variables such as {run_id}:
3. Write verification scripts
The verification script runs within Docker, and the result is written to_test_results.json. This is the source of the determination for “whether this operation was correct or not” :
failed list reported by the verification script is empty. Both pass@k and pass^k are based on this determination.
4. Write a Dockerfile
Dockerfile provides the runtime and dependencies required for validation. A minimal example:5. Register the task
Finally, register inlocal/tasks/index.yaml:
--task my-task.
Configure Treatment
Treatment replied, “What skills were injected into this run?” Located atlocal/treatments/:
Select “Profile”
Profile decides which rubric scoring system to use. If you choose the wrong profile, the dimension score will have no reference valueProfile resolution priority:
— PROFILE coverage > manifest’s
skill.profile > The task of evaluation. Profile & gt;
generic. Comet-like tasks (category = “comet”
It will be automatically inferred as comet-workflow.Configure LLM-as-judge
LLM-as-judge is an optional quality overlay. It will not replace the regular[RUBRIC] score, nor will it directly change weighted_score. It will have an independent referee model read the product of this run, append the [RUBRIC-JUDGE] score, and help you determine whether the “product has substantive content” that is not covered by the rule score.
Suitable for enabling in these scenarios:
- You need to evaluate documents, plans, code explanations, design drafts and other products that are difficult to be fully judged by scripts.
- You already have a basic verification script, but you want to know if the product is just an empty shell or template-based content.
- You need to check the difference between the rule score and the judge score in the comparison report.
The configuration of judge and that of the Agent under test are isolated. The Agent under test can continue to use
ANTHROPIC_MODEL, ANTHROPIC_BASE_URL and their own
token;” judge must explicitly configure BENCH_JUDGE_MODEL
Avoid having the same configuration act as both a “player” and a “referee” at the same time.Enable judge in eval/.env
Write the judge variable into the Comet repository’s eval/.env:
BENCH_LLM_JUDGE=1 is a switch. BENCH_JUDGE_MODEL are required fields. When the switch is turned on but the model is not set, the report will be written to the skipped state:
2. Select the authentication method of judge
If your localclaude CLI can already be authenticated on the host machine, you can only set BENCH_JUDGE_MODEL. The harness will call the claude CLI on the host machine to run judge.
If you want judge to use an independent Anthropic compatible proxy, configure dedicated endpoints and tokens:
If
BENCH_JUDGE_AUTH_TOKEN and BENCH_JUDGE_API_KEY are set simultaneously, the auth token
Priority. The judge child process will clear the inherited main ANTHROPIC_* provider variable and then map it
So don’t expect it to automatically reuse the provider configuration of the Agent under test.3. Add a custom judge standard to generic task
The general Skill (generic/authoring-skill) will by default make judge output three dimensions:
If your task also has specific quality standards, write them into
task.toml’s [evaluation]:
custom_0 and custom_1. They only affect the [RUBRIC-JUDGE] overlay and do not replace your verification script.
The comet-workflow profile uses another set of judge dimensions: artifact_quality, spec_drift, and main_flow. They are used to review the depth of workflow products, whether the spec has drifted, and whether the five-stage main process is complete.
4. Run and confirm that judge is effective
First, use--collect to confirm that the task, manifest and path can all be found:
Report path and look for the [RUBRIC-JUDGE] line in each run of checks. When you succeed, you will see something like
Multi-round interaction: auto_user mode
Single-round task (mode: none) runs only once and is suitable for simple scenarios where “a command is given and the result is seen”. However, workflow-related skills need to be paused at the decision point, ask the user, and resume after receiving a response - single-round testing is not possible.
The auto_user mode solves this problem: it uses ** two agents to interact automatically ** - one runs the Skill (subject) under test, and the other simulates the user’s response at the decision point (simulator).
The behavior of the simulator is controlled by the prompt word file. By default, it reads eval/simulator-instruction.md. You can use BENCH_SIMULATOR_PROMPT_FILE to point to your own version, simulating a “more picky user” or a “user who will ask for clarification” :
max_turns controls the outer-loop cap (comet-workflow is commonly 12 outer round trips, authoring-skill commonly 8). It is not the number of internal messages or tool calls of the tested Agent. One outer round trip means: the tested Agent reaches a decision point, the user simulator responds, and the tested Agent continues with --resume. A completion signal (such as archive complete) can end the loop early.
A complete custom assessment
String together the above steps and evaluate your Skill from scratch:pass@1andpass^k: upper capability versus the reliability floor. See Scoring metrics.- **rubric Dimension Scores ** : Which dimension is holding back?
- Failure attribution of ** ** (
harness/workflow/task/model) : failure is the issue of Skill, or a task/environment problems?
Review the package generated by /comet-any
The Skill package generated by /comet-any comes with the comet/eval.yaml manifest, so you don’t need to write task.toml by hand. Run directly with manifest:
authoring-skill profile, injects recommended tasks, and applies quality gates. See the complete format in Evaluation system overview.
Next step
- Scoring metrics and Dual-Agent evaluation - Dimensions, weights and pass@k/pass^k of three sets of rubric
- Evaluation system overview - manifest format, profiles, and tasks
- comet eval command - Complete reference for command-line parameters