Look at these first when reading the report
If you are not debugging the scorekeeper, you can read the report in this orderWhen making daily release judgments, don’t just look at
weighted_score. The true pass/fail first looks at checks_failed; rubric, pass@k and pass^k are used to determine quality, stability and the direction of the next optimization.Scoring metrics
Key distinction: rubric dimension scores and pass@k/pass^k are informational metrics used for diagnosis and comparison. Actual pass/fail is determined by
checks_failed == []. Most failures come from task validators (the existence of target_artifacts plus test_scripts), but a profile can also add Workflow Contract failures, such as a required Skill not being invoked, to checks_failed.Where does the evidence come from
Comet eval collects runtime evidence from Claude CLI stream-json, task artifacts, validator results, and Runtime state. The single-round evaluation will directly run the Agent under test in the task directory of Docker:stdout/stderr of this run and then parses the JSONL events in stdout line by line. The parser will extract:
- The
duration_ms,num_turns, token and cost in theresultevent - Tool calls in the
tool_useevent - The
Bashcommand, ascommands_run - The file path of
Write/Edit, asfiles_created/files_modified - The
Skillcall, asskills_invoked - The corresponding
tool_resultoutput is hung back to the original tool call
Skills invoked, commands_run, tool_calls, files_created, token/cost, etc. in the report are all observable behavior logs sorted out from the structured event stream of Claude CLI.
Trajectories and event streams are not the same thing
Comet Classic runtime itself also writes.comet/trajectory*.jsonl to record state progress, such as state_transitioned. This type of trajectory is one of the pieces of evidence of recovery ability. rubric will check whether it exists in recovery_resilience.
But pass@k/pass^k does not calculate from the trajectory, and most of the dimensions of rubric do not look only at the trajectory. The main sources of evidence are Claude CLI stream-json, the products in the task directory, the results of the task validator, and the status files left by Comet runtime.
rubric score
rubric breaks down the quality of Skill into multiple dimensions, each of which consists of several binary (pass/fail) checkitems. The dimension score = the number of passed items/the total number of items (0.0-1.0). Output a line of[RUBRIC] < Dimension >: < Fraction > - < Cause > for each dimension.
Scoring methodology (aligning with industry practices such as Galileo, Hebbia, and τ-bench) :
- Each dimension contains N binary checkitems
- Dimension score = passed/total (0.0-1.0)
- Weighted total score = Σ(Dimension score × weight)/Σ(weight)
- The weight reflects the importance of dimensions to the quality of the workflow
Three sets of rubric
eval comes with three sets of rubric, corresponding to three profiles:comet-workflow rubric (10-dimensional)
Evaluate the classic five-stage workflow. The ten[RUBRIC] dimension scores themselves are diagnostic scores; However, the profile will still check the Workflow Contract: if comet, nested Comet stage skills, OpenSpec dependent skills, or Superpowers dependent skills are not actually triggered, a hard failure will occur.
generic rubric (7-dimensional)
Evaluate general skills. Unlike comet-workflow, ** It causes a hard failure when “the required Skill is not called” ** (whenrequire_skill_invocation: true), while the rest of the dimensions are informative.
authoring-skill rubric (11-dimensional)
Evaluate the Skill package generated by/comet-any. It first inherits the four shared dimensions of generic and then adds seven package-specific checks. Missing SKILL.md, missing resolven-skills.json, missing workflow-protocol.json, missing Engine file, missing authoring-lanes.json, missing skill-review.md All of them will result in hard failures.
Weighted total score formula
[RUBRIC] <dim>: <score> - <reason> for each dimension, and finally output one line of [RUBRIC] weighted_score: < points >.
RubricAvg (Report Column)
TheRubricAvg column in the report is the ** simple average score ** (sum/len) of all dimension scores (including the weighted_score row) of this run. When running across multiple runs, it is the average of the average scores of each run. It is a summary of rapid horizontal comparison, which is different from the single rubric weighted_score (using their respective weights) algorithm.
LLM-as-judge coverage (Optional)
EnableBENCH_LLM_JUDGE=1. By default, Comet’s final weighted_score is rule-based, not LLM-as-judge. Rule rubrics capture structural signals (file existence, command execution), but they cannot judge whether output has real substance. The LLM judge reads workspace artifacts, re-scores them, and emits a [RUBRIC-JUDGE] line (separate from the rule-scored [RUBRIC] line). If judge execution fails, scoring falls back to rule results without blocking execution.
judge runs on the host machine (not within Docker) by reusing the claude CLI without introducing new dependencies. However, the configuration of the referee and the configuration of the Agent under test are deliberately isolated: when BENCH_LLM_JUDGE=1 is enabled, BENCH_JUDGE_MODEL must be explicitly set, and it is not possible to fall back and reuse the ANTHROPIC_MODEL of the main model.
If BENCH_JUDGE_BASE_URL and BENCH_JUDGE_AUTH_TOKEN/BENCH_JUDGE_API_KEY are configured, judge will give priority to directly invoking Anthropic Messages HTTP (/v1/messages). When there is no dedicated judge endpoint, roll back to the host claude CLI, clear the inherited main ANTHROPIC_* provider Settings in the child process, and then map the independent judge configuration to your own CLI call:
This design is to avoid the situation where “the same model acts as both the player and the judge” : the main Agent can continue to use its own
ANTHROPIC_MODEL, ANTHROPIC_BASE_URL and token, while the judge must declare the model and provider separately. The direct HTTP path can also avoid the problem that some strictly Anthropic compatible proxies do not accept additional request parameters from the Claude CLI. If BENCH_LLM_JUDGE=1 is enabled but BENCH_JUDGE_MODEL is missing, the report will be written as
enabled_and_successful, nor will the referee model be invoked.
Different profiles cover different dimensions:
The three-dimensional scoring criteria of generic/authoring:
When judge collects workspace files, it skips directories such as
.git, node_modules, and .comet. The upper limit for a single file is 3,000 characters, and the total budget is 20,000 characters. Large files (>50KB) and binary files will be skipped to ensure that the prompt does not get out of control. The referee must output line by line in the [RUBRIC-JUDGE] <dim>: <score> - <reason> format, with each reason no more than 25 words and specific content cited.
pass@k and pass^k
These two indicators measure “ability vs. reliability” and are the key to evaluating whether a Skill can run stably and repeatedly. They are calculated based on the pass/fail sequence of ** repeated runs **.Definition
Here, n = total number of runs, and c = number of successful runs. “Success ”= Zero failure of the task validator in this run.
Why do we need two?
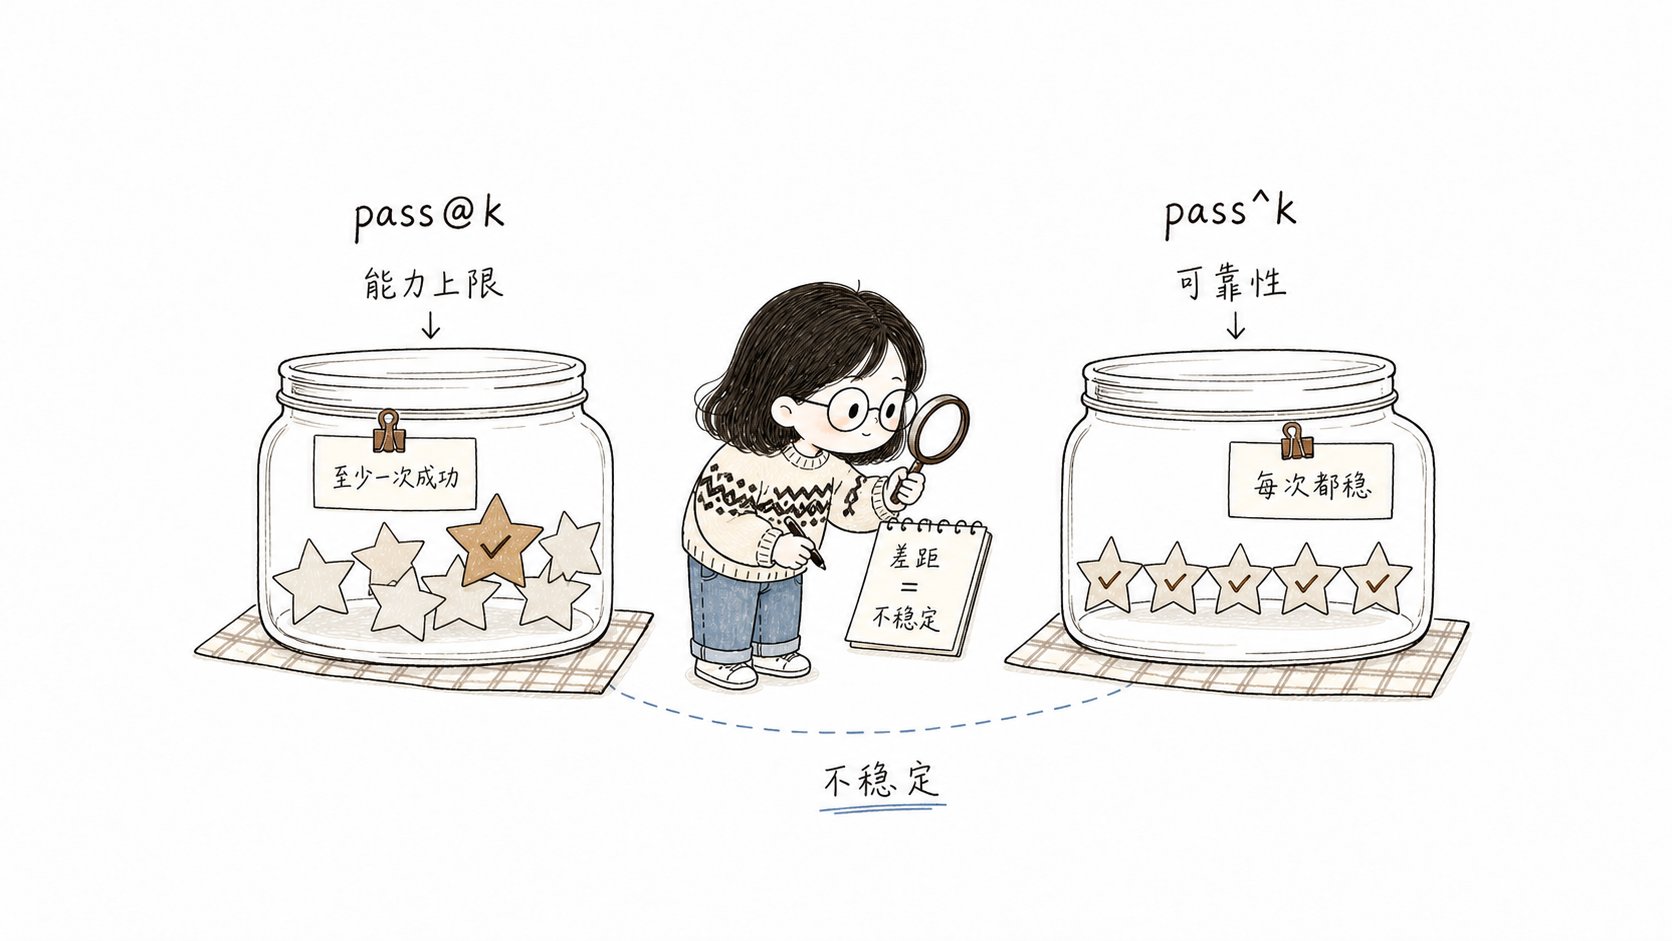
pass@k check the upper limit of capacity, pass^k check the lower limit of reliability. The greater the gap between the two, the more unstable it is.
- **pass@k high, pass^k low ** : Sufficient ability, but ** unstable ** - “Can do it, but cannot guarantee to do it right every time”. Repeatedly running a Skill to a user is a danger signal.
- Both are high: they can do it and do it right every time - reliable.
pass@k − pass^k as a comparison of repeated-run results.
How can I get multiple runs
Repeated runs are driven by the eval harness’s internal pytest option--count N: it repeats each (task, treatment) combination N times to generate N independent pass/fail results (comet eval only produces pass@1/pass^1 from a single run). The comparison report first filters out the analysis set: explicit environment issues or problems with the runner itself will be excluded, and flagged run still enters the main statistics but will be marked. The N Boolean values in the analysis set are the input of pass@k/pass^k.
How to choose k
The report takes the k value from{1, 2, 5} that does not exceed the actual running number n (k is clamp-down to n), and if it is insufficient, it reverts to [1]. Report columns: pass@1 [pass@2 pass@5] and pass^1 [pass^2 pass^5].
Where is it?
pass@k/pass^k is not insummary.md, but in the ## pass@k/pass^k — capability vs reliability section of the ** Comparative report ** (comparison_report.md). They are informative, not access control.
Dual-agent automatic interaction evaluation
For multi-stage workflow skills (comet-workflow and authoring-skill profiles), the evaluation is completed by the automatic interaction of ** two agents **, without the need for human intervention.
Two roles
Interactive loop
The loop has a maximum ofmax_turns outer round trips (comet-workflow is commonly 12, authoring-skill commonly 8). It ends early when a “Complete” signal is detected (archive complete, workflow complete, all 5 phases, and similar markers).
Each round of the tested Agent is run with --output-format stream-json --verbose. The loop driver only concatenates the stream-json stdout of each round of the Agent under test for harness parsing. One-time responses from the user simulation Agent will not enter the main event stream. Therefore, event statistics only reflect the observable behavior of the subject Agent.
max_turns is neither the actual number of working rounds within the Agent under test nor the number of tool calls. An outer round trip refers to: the Agent under test runs to the decision point, the user simulates the Agent’s response, and then the Agent under test continues with —resume. The same round trip may still contain multiple assistant messages, tool calls, and file operations internally.Decision point detection
If the output text of the Agent under test matches these signals, it is determined as a decision point (case-insensitive) :--decision-pattern.
The user simulates the instructions of the Agent
The simulated Agent receives the simulator prompt + the last message of the Agent under test, with the following instructions:- When it receives a confirmation request, ** approve ** the proposed scheme/name/plan
- When it needs to make a choice, ** select the most reasonable default **
- Only ask for clarification when the question is truly ambiguous about “what to do”
- Never refuse, always keep the workflow moving forward
- “Do not write code or files.
COMET_SIMULATOR_PROMPT, and generic/authoring uses GENERIC_SIMULATOR_PROMPT (the wording is slightly simplified). When the simulation response is empty, roll back to "Yes, please proceed with the recommended option.".
Customize the simulator prompt word
The simulator instructions evaluated by auto_user can be overridden. By default, it reads fromeval/simulator-instruction.md, and its content is the standard template of the above principles. Two coverage methods (priority from high to low) :
The relative path of
BENCH_SIMULATOR_PROMPT_FILE is resolved from eval/, with the default value simulator-instruction.md. When the file exists, replacing it lets you test different user behavior profiles without modifying the harness.
Design purpose
Workflow skills will pause at the decision point and wait for user confirmation. If the evaluation only runs a single round, Skill will get stuck at the first decision point. The dual-agent loop enables the evaluation to automatically run the entire workflow (open→…) →archive), and the user simulates the Agent to generate reasonable decision point inputs that can drive the process. Only in this way can the rubric score and pass/fail measured reflect the real usage scenarios.Single round vs. multiple rounds
genericprofile (interaction.mode: none) : Single-round, the Agent under test runs all at once (suitable for smoking tasks that do not require interaction).comet-workflow/authoring-skillprofile (interaction.mode: auto_user) : Multi-round, enabling dual-agent loop.
comet-* or category: comet will be automatically inferred as comet-workflow profile and auto_user will be enabled.
The three axes of evaluation: treatment × task × reps
One evaluation is the Cartesian product of three axes:The treatment achieves A/B comparison
Running multiple treatments for the same task can measure the marginal effect of Comet Skill:
The comparison report (
compare_baselines.py) compares COMET_FULL (WORKFLOW) and COMET_FULL_039 (BASELINE) across rubric dimensions, with CONTROL only serving as the context.
How can indicators be included in the report
For details, please refer to Read the Evaluation Report ]
Next step
- Read the evaluation report - Report structure and failure attribution
- Eval harness - collect/run internal mechanism and environment variables
- Overview of the Evaluation System ](/en/eval/overview)-Eval in the release process
- comet eval command - Complete options reference