For daily evaluation you only need the installed
comet eval and a user-level .env; there is no need to clone the Comet source code. You only need to pull the source when modifying the evaluation harness itself or reproducing historical experiments.comet eval is the universal Skill assessment entry for Comet. It first answers a question: ** Can the Skill in your hand qualify as a reliable product capability and be evaluated through real tasks? **
This page has two parts:
- First, look at how your skills are evaluated: entry points, tasks, scores, reports, and failure attributions.
- Let’s take a look at how
/comet-anyintegrates the eval result into the release readiness.
Start from here
Evaluation output
For daily use, just focus on the evaluation tasks and results.comet eval has encapsulated the startup details of pytest, task registry, profile, treatment, Docker and local eval harness. You can directly run the evaluation in the project root directory.
Two evaluation systems
Comet has two evaluation systems, which have similar names but are completely different:comet eval answers the question “Can this Skill pass the assessment as a product capability?” and executes real model tasks through the shared eval harness. When comet skill check answers “Is there a missing file or status during this Skill run?”, it only checks the runtime check items and does not run the model. For details, see Runtime check.
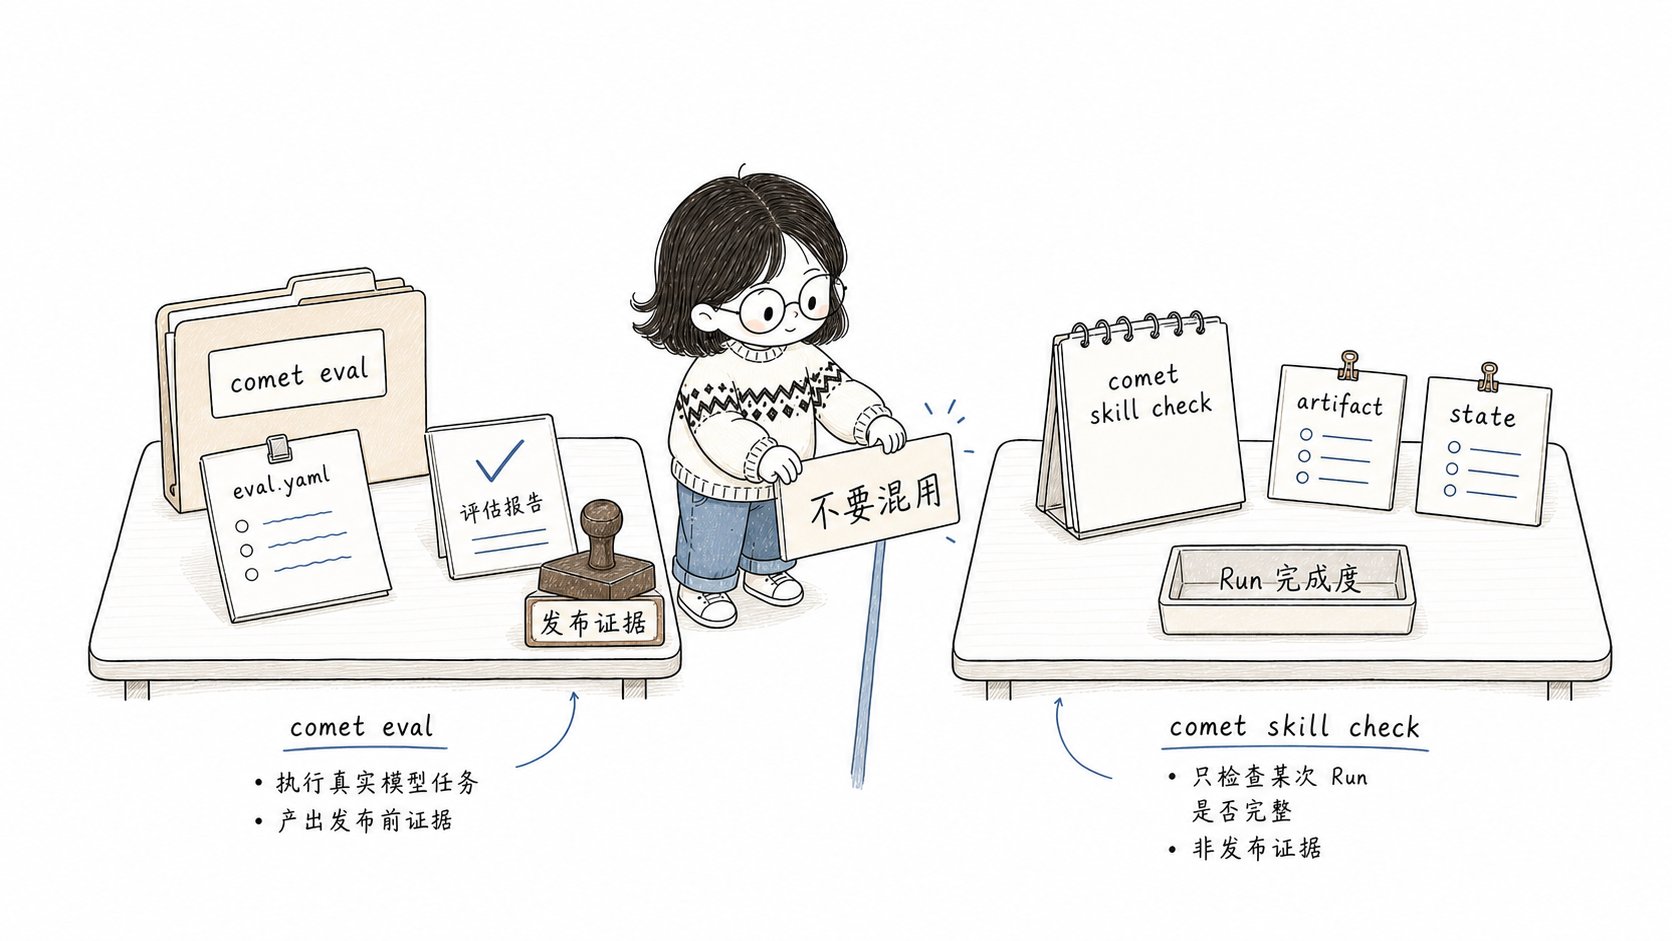
comet eval produces pre-release evidence, while comet skill check only checks a certain Skill
Whether the operation is complete or not, do not mix the two
The first part: How is one’s own Skill evaluated
From the user’s perspective,comet eval does four things:
- Find your Skill.
- Find out which assessment tasks should be run.
- Let the model perform tasks in an isolated environment and check the results with a validator.
- Generate a report to tell you the reasons for passing, failing and the next steps.
How to choose the entrance
comet eval [target] automatically determines the entry point based on the target: when passing to a directory or SKILL.md, it uses the skw-path; when passing to comet/eval.yaml, it uses the manifest. Both can also be explicitly specified using --skill-path/--manifest, with explicit entry mutual exclusion.
When transferring directories, the manifest will be automatically discovered. When there is no manifest, normal operation will generate and cache 2 to 4 restricted tasks from the Skill snapshot.
--quick is the fixed generic-skill-smoke that smokes. --skill-name will automatically infer from the directory name. No comet/eval.yaml is needed, nor is it necessary to clone the Comet repository - the npm package comes with an eval harness.
Run collect first
collect is the cheapest troubleshooting entry point for users. It only performs discovery and pre-checking, and does not execute model or Docker tasks. It is suitable for quickly identifying path, manifest, task cache and configuration issues.
- Is the
comet/eval.yamlpath correct - Whether eval harness can read this manifest
- Can the recommended tasks in the manifest be discovered
- Is the eval dependency path of the current repository available
comet/eval.yaml manifest
comet/eval.yaml is a complete list of evaluations before release. It tells the eval harness: where the Skill is, which profile to use, which tasks are recommended to run, and which evidence and artifacts are expected. Its format is parsed by the eval harness:
/comet-any defaults to using the authoring-skill profile. For regular workflow-kernel, generic-skill-smoke, authoring-skill-smoke and workflow-route-conformance are recommended. The overlay based on /comet will additionally recommend workflow-overlay-contract and the classic Comet workflow task to check the Output Schema, expected evidence and overlay routing.
Profile
eval harness has three built-in profiles, each determining the rubric dimension, default interaction mode, and scoreer:
Profile parsing priority:
--profile overwrite > manifest’s skill.profile > task’s evaluation.profile > generic.
maxTurns is not the number of internal messages of the Agent or the number of tool calls. It only takes effect in the auto_user mode, restricting the maximum number of outer round trips such as “the Agent under test runs to the decision point -> the user simulator replies -> the Agent under test continues with —resume”.Tasks starting with
comet-* or metadata.category=comet
The task will be automatically inferred as comet-workflow profile, and the interaction mode will be automatically switched to
auto_user ( two agents interact automatically : one runs under test.
Skill, another simulated user replies at the decision point.Scoring criteria: rubric + pass@k/pass^k
eval is an ** metric driven ** evaluation, not just for pass/fail:- **rubric Multidimensional Scoring ** : The Skill quality is split into multiple dimensions (such as the five-stage main_flow/gate_guard, safety_boundary for general Skill), with each dimension ranging from 0.0 to 1.0, and weighted and aggregated into
weighted_score. Used for diagnosis only, not as a gate. - pass@k/pass^k : distinguish between ** upper capability ** (at least one success out of k attempts) and ** lower reliability ** (all success out of k attempts). Calculated from multiple repeated runs (repeated runs are driven by the eval harness’s internal pytest option), likewise used for diagnosis only.
- ** Task Validator passes/fails ** : Is this implementation correct or not (
target_artifacts+test_scripts)? This is the hard-judged pass/fail.
Task
eval harness has a built-in set of tasks, each of which is a directory (includinginstruction.md, task.toml, environment/, validation/). Common tasks
recommended is the default parsing path of CLI: when --manifest is used, the manifest’s recommendedTasks is read. Run the default_treatments of each task when there is no manifest. It does not represent a specific task name.
What does the default entry of skill-path run
When passing a local Skill directory, the normal runtime will generate and cache restricted tasks based on the Skill snapshot. When a fixed quick smoke is required, explicitly use--quick:
- Whether the Skill directory is readable
- Can the eval harness be injected as a dynamic Skill
- Can the general smoke task run and produce
result.md
/comet-any (with comet/eval.yaml).
Part 2: How to connect /comet-any to eval
/comet-any is responsible for creating or optimizing the Skill, and comet eval is responsible for verifying whether this Skill can be discovered, run and generate reports by the eval harness. The connection point between the two is comet/eval.yaml in the product and Eval evidence after evaluation.
Complete link
comet eval is not responsible for the release. Publication is still handled by the creator/publish command: the creation and restoration of status are exposed through comet creator], and publication and distribution are exposed through comet publish]. The responsibility of eval is to provide pre-publication evidence.
Recommended path: Evaluate the Skill generated by comet-any
When/comet-any generates a Skill, the first file to look for is:
collect, only confirms “whether the task can be discovered”, which is suitable for conducting a low-cost pre-check right after generating the Skill. The second step is for run --html to conduct a real assessment and generate a browsable report.
How do Eval results enter publish readiness
/comet-any or the creator/publish backend will incorporate the Eval result into publish readiness after logging it. There are only two points that the user needs to know
- The results produced by
comet evalwill serve as the source of evidence forPublish readiness:. - When the current hash lacks Eval evidence,
User next steps:must first point to the completion evaluation and suspend the release.
comet creator next only outputs the currently recommended one-step user command; comet publish review will display Publish readiness:, User next steps:, Readiness:, Blockers:, Warnings: and Evidence: to users.
How does /comet-any use eval results
From the user perspective, once eval completes, return the result to/comet-any and continue. /comet-any incorporates eval evidence into readiness:
Users do not need to manually edit the internal state, nor should they manually write the report path into JSON.
/comet-any will record structured evidence through the backend.
Common sequence
- The core issue of
comet evalis: Can this Skill, as a product capability, be evaluated through real tasks? - Any local Skill directory can be used to run Docker evaluations with
comet eval ./your-skill. When it is time to release, evaluate the complete package generated by/comet-any(withcomet/eval.yaml). - First
collect, thenrun --html. - The
/comet-anyproduct will access the eval result to the release readiness, but eval itself is not a release action. comet eval(creation period) andcomet skill check(runtime period) are two separate systems and should not be used interchangeably.
Next step
- Scoring criteria and dual-agent evaluation - rubric dimension details, pass@k/pass^k, dual-agent interaction loop
- Eval harness - Understand the internal mechanisms, environment variables, and report generation of collect and run
- Read the evaluation report ](/en/eval/reports) - Learn to understand the report signals and failure attributions
- Runtime check - Distinguish between
comet evalandcomet skill check - comet eval command - Complete options and subcommand reference