comet eval ... --html will generate a browsable report. Users do not need to read the underlying logs line by line. They should first look at the results, attributions and products, and then decide on the next step.
Report location
--html will require the report to produce both markdown and HTML simultaneously. The CLI output will include Experiment and Report path. Common locations:
<experiment-id> is <experiment_name>_<YYYYMMDD_HHMMSS>, for example, authoring_skill_smoke_20260625_143000. The “experiment name” comes from the task name of the first parametric test (- to _; experiment is the default when there is no test).
If the CLI output shows placeholders, search the same output block for the actual Experiment value. You can also find the matching experiment in:
Report table of contents structure
.comet/eval/runs/<experiment-id>/
summary.md
summary.html
metadata.json
events/
raw/
reports/
artifacts/
reports/<treatment>_rep<n>_report.json: The complete result of each run, includingpassed,checks_passed[],checks_failed[],events_summary(tokens/cost/skills_invoked/failure_attribution).metadata.json:experiment_id、started_at、completed_at、total_runs、total_passed、treatments[]、report_outputs。
What to look at first?
After opening the report, first look at the following types of summary information. The underlying logs will be read when specific issues are investigated- ** Evaluate whether it is passed ** (output at the top of summary/CLI)
- ** Failure attribution ** Is it harness, workflow, task or model
- Whether the failed use cases are related to the Skill goals
- Is the expected artifact (hard verification) missing?
- Is it a problem with the path, manifest or environment
- Is token/cost/duration abnormal
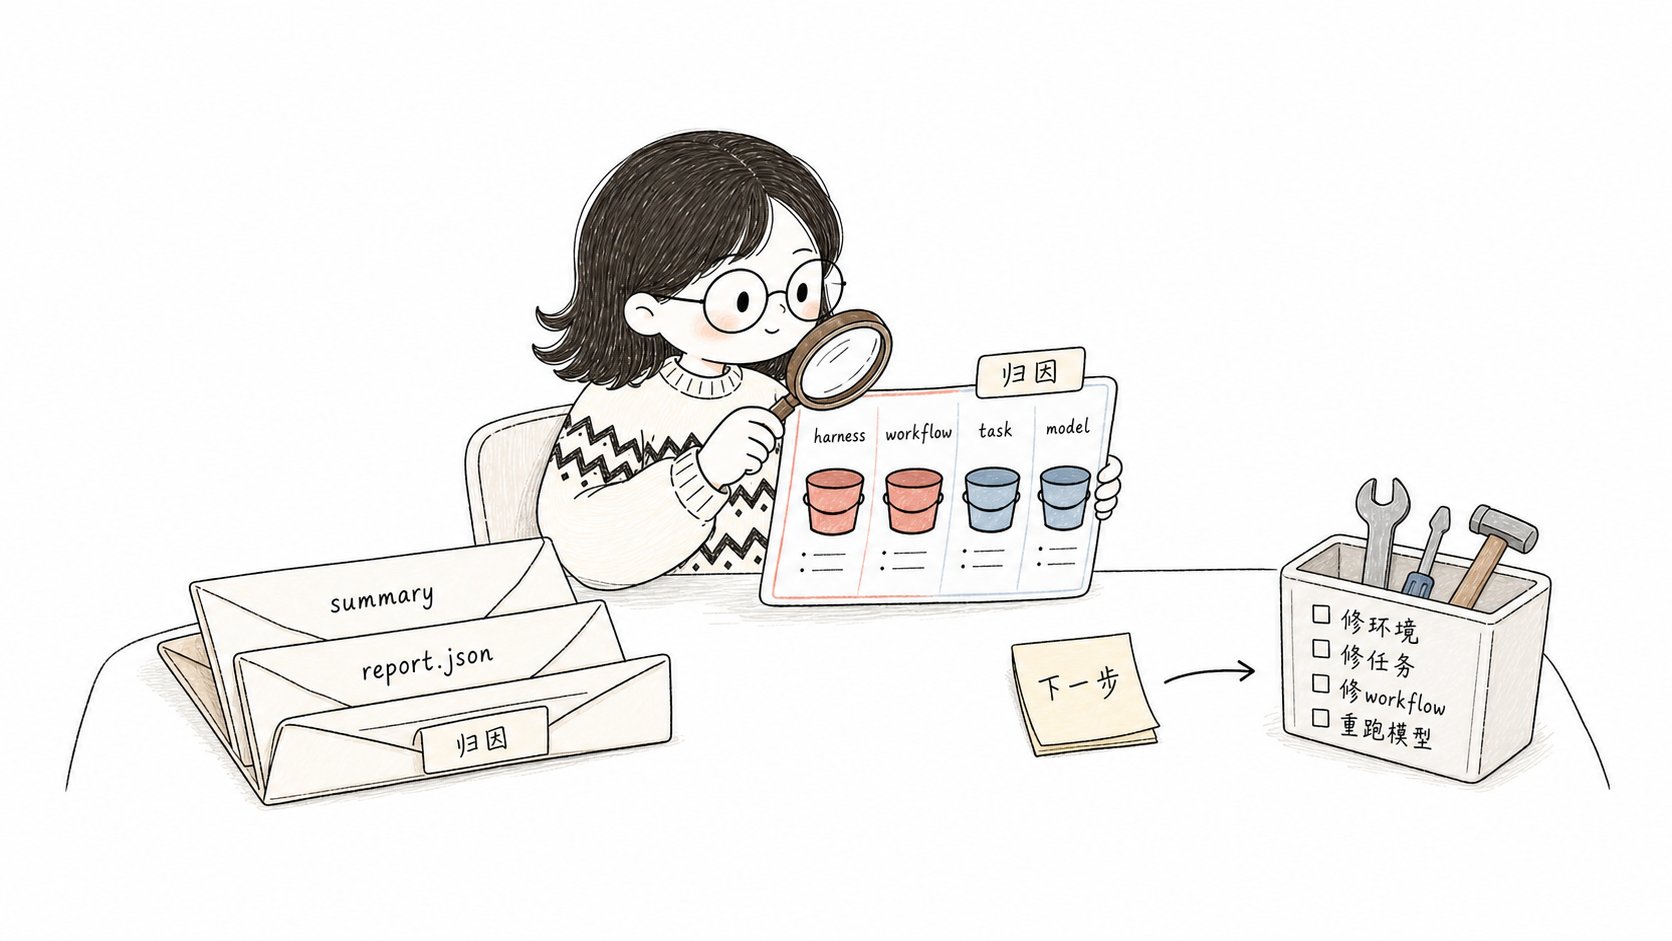
First, look at the summary, then check the single report, and finally use failure attribution to determine the next step
Failure attribution
The output ofcomet eval ... --html will prompt failure attribution: The report will attribute the failure to the four buckets of harness, workflow, task, and model. The attribution logic is judged in sequence:
Rubric Score (Informational)
The report will contain rows[RUBRIC] <dim>: <score> - <reason> and columns RubricAvg for summary. This is an informative score and does not directly determine whether one passes or not. Dimensions of different profiles
The “rubric” column in summary.md
The Results table has one row for each treatment, and the column order is:Checks → columns for each rubric dimension → RubricAvg → Turns/Duration/Tools/Tokens/Cost.
- ** Dimension Column ** : A single run shows the score of this dimension (0.00-1.00); Multiple runs (reps) show the mean.
- RubricAvg: the simple average of all dimension scores in that run (including the
weighted_scorerow) — a quick cross-run comparison summary, computed differently from a single rubric’sweighted_score, which weights each dimension. - weighted_score: the rubric’s weighted total (
Σ(dimension score × weight) / Σ(weight)), presented as a column.
Aggregation when reps > 1
When runs are repeated (driven by the eval harness’s internal pytest--count N), the summary will have an additional “Aggregated by Treatment” table: Reps Passed (number of repeated passes), Checks, Avg Turns/Duration, Tokens, Cost, Skills, Scripts. Each repeated pass/fail (zero checks_failed means pass) is aggregated and used to calculate pass@k.
Rubric is a diagnostic tool, not a pass condition.
. The actual pass/fail is determined by the validator (expected artifacts, test_scripts) and “required skill
Whether it is called or not is decided. The Rubric score was low but all the checks were passed, so it still counts as passing.
pass@k/pass^k (comparative report)
pass@k/pass^k is not insummary.md, but in the ## pass@k/pass^k — capability vs reliability section of the ** Comparative report ** (comparison_report.md, produced by compare_baselines.py) :
- pass@k : the probability of success at least once out of k attempts (upper limit of ability)
- pass^k : The probability of success in all k attempts (lower reliability limit)
- **gap (pass@k − pass^k) ** : instability - it can be done but cannot be guaranteed to be correct every time
How to decide on the next step
How to determine which stage it is when a failure occurs
collect failed
Priority inspection- Is the manifest path correct
- Does
comet/eval.yamlexist - Whether the recommended task in the manifest exists
- Is it currently in the root directory of the Comet repository or has the correct
--projectbeen passed
”run failed”
First, look at the failure attribution in the report and locate according to the bucket above. Let’s take a look atevents_summary in reports/<treatment>_rep<n>_report.json:
skills_invokedis empty → harness attribution, the Skill did not runfiles_createdlacks expected artifact → Skill does not produce the expected file- If
total_tokensis abnormally low, it may lead to the premature termination of Skill
”Instant pass” evaluation
It is almost certain that the suite was skipped because the environment was not ready. Check Docker, model credentials and the selected Agent CLI.The HTML report was not found
First, look at the CLI output ofExperiment and Report path. If there are placeholders in the path, use the actual experiment id to search in the .comet/eval/runs/ directory.
How can the report be released
Do not manually edit the Bundle status, nor manually write the report path into the internal JSON. Have the/comet-any or Bundle backend record the eval result and have comet creator status read the readiness.
The rules for Eval evidence to enter readiness:
Next step
- Runtime check - Distinguish between
comet evalandcomet skill check - comet eval command - Complete options and subcommand reference
- How does publishing and distributing Skill](/en/skill-creator/publishing)-eval evidence drive readiness