The boundary with Rule and the project Wiki
Rule remains the explicit constraint entry
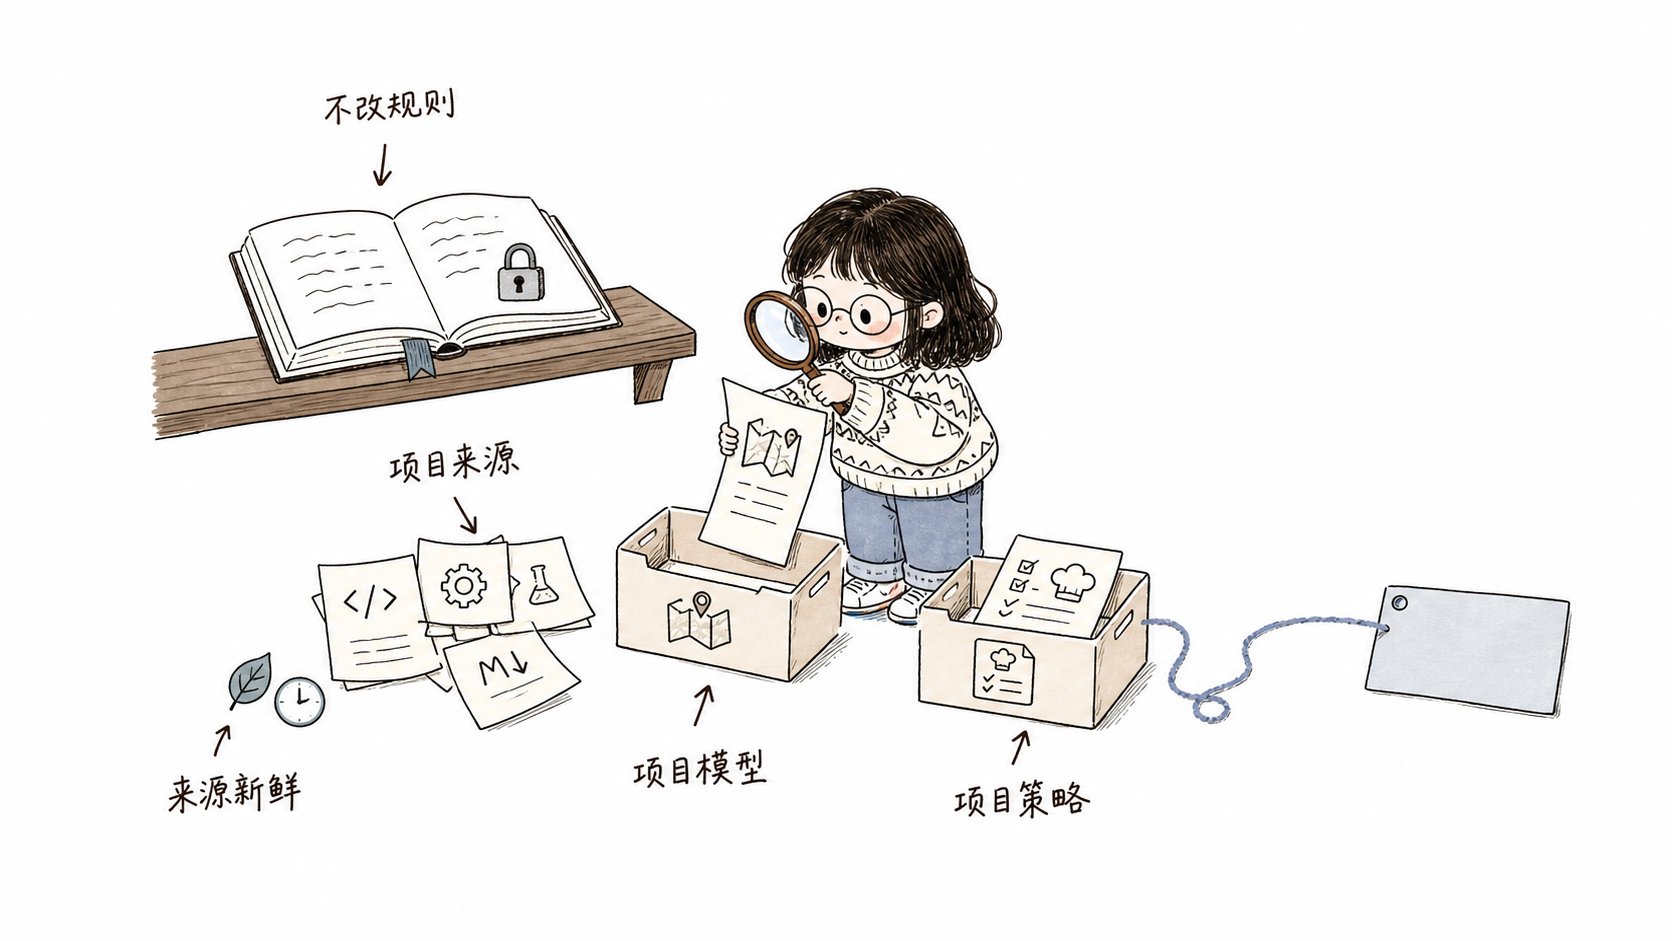
Project Knowledge does not replace Rule. You can keep writing team directives and behavioral constraints in the Rule files or rule directories your target platform supports, such asAGENTS.md for Codex, CLAUDE.md for Claude Code, .cursor/rules for Cursor, and the Rule carriers other platforms provide. The platform still loads this content according to its own scoping rules.
Comet does not take over Rule authoring or loading, and it never silently rewrites a Rule. When a Rule is configured as a knowledge source, Project Knowledge can cite its basis and scope; the original Rule stays the higher-priority project evidence.
Project Knowledge accumulates per task, not as a full Wiki
Project Knowledge does not offer “one-click project Wiki generation”. Comet does not scan and explain every directory, file, or implementation detail in the repository, and it does not promise to produce human documentation that covers the whole project. Project Knowledge is scoped to the Agent’s later tasks. It only keeps records that help locate an entry point, complete a change scope, understand a decision, or pick a verification method. Ordinary details without a reliable source, valid only for the current task, or directly readable from the source code are not stored long term just to fill a knowledge base.Core capabilities
The core goal of Project Knowledge is a better first-hit quality and a more complete change scope. Retrieval speed is only a means; the real effect depends on whether the Agent finds the right entry point, related files, and verification path earlier.
Industry practice and where Comet fits
The industry typically gives coding agents project context through three kinds of capability:- Project instructions: Codex uses
AGENTS.md, Claude Code usesCLAUDE.mdand path-scoped rules, and Cursor uses Project Rules. They fit behavioral requirements a team writes down explicitly. - Code indexes: tools such as Sourcegraph Cody index the code so agents can find symbols and related fragments.
- Agent knowledge layers: the Qoder Knowledge Engine organizes architecture, engineering conventions, and cross-file relationships into reusable project understanding.
AGENTS.md short and pointing to structured repository knowledge. Short instructions stay focused, while detailed knowledge can be loaded per task and maintained separately.
Comet splits these three kinds of capability further:
- Repository Rules hold the Agent instructions the team wrote explicitly;
- Project Knowledge holds engineering understanding with sources, scopes, and a lifecycle;
- Full-text and exact search recall relevant candidates;
- Hooks, linters, tests, builds, and CI perform the actual rule checks and enforcement.
What Project Knowledge records
Content becomes a normalized Project Knowledge Record only when it has a source, can be given an applicable scope, and helps later tasks:- Directory, module, and workspace topology;
- Facts that can be checked against the current repository;
- Dependencies between modules, packages, and components;
- Accepted design and product decisions;
- Stable implementation patterns and operation flows;
- Project constraints and failure-resolution experience.
Two kinds of Project Knowledge
Project Model
Project Model stores structures and facts that can be verified against the current project’s evidence:
Module records include entry points, dependencies, callers, registration points, and related tests for the Agent to expand as needed. The Local Provider restores missing or stale model records and consolidates duplicate generated history.
Project Policy
Project Policy stores engineering practices accumulated through real work:
A Project Policy can enter the
enforced (verified constraint) state only after its bound verification command currently exists and has run successfully. In the Native workflow those verification commands run together with the necessary Verify-phase checks (see Verification and repair), and the policy is promoted only when they pass. enforced means the project already has a tool that can check this policy; the natural-language content is still provided to the Agent as context.
Project Memory: experience the Agent writes directly
Project Memory is the file-based experience layer inside Project Knowledge. Unlike Project Model and Project Policy, it skips extraction and the review queue: at the end of a task, the Agent writes verified, reusable lessons directly throughcomet knowledge remember, and they take effect for later tasks immediately.
--type accepts fact, decision, pattern, procedure, constraint, or failure-resolution and defaults to pattern. The same title updates the same memory by default instead of stacking duplicates.
Project Memory is stored outside the repository in the local knowledge-cache directory: one MEMORY.md index plus one Markdown file per lesson. The Dashboard’s project memory page shows the exact storage location.
Injection and expansion
- The
MEMORY.mdindex is injected in full with every task context; the index is ordered newest first, so a tight context budget keeps the newer lessons. - To read one lesson in full, append
--expand-context "project-memory:<slug>"with the same task arguments. - The index is read before Local/Remote provider retrieval, so Project Memory still applies when a provider is unavailable.
comet task --completereminds the Agent in its tool response: if this task produced verified, reusable, and not-yet-recorded project experience, record it now withcomet knowledge remember; otherwise skip.
Management entry
comet knowledge forget . --memory <slug> deletes stale project memories. The Project Memory tab on the Dashboard’s Project Knowledge page is a read-only view where you can browse, search, inspect, and delete project memories; the recently-used list shows when the memory index was last delivered to the Agent.
Relationship with Rule, Hook, and engineering checks
Project Knowledge provides understanding, Rule provides instructions, and Hook and engineering checks handle enforcement.Repository Rules, source code, configuration, tests, and checks always stay the higher-priority evidence. Comet reads and links these sources; it never silently rewrites them.
How Project Knowledge forms
Establish a base Project Model
The Local Provider builds a limited Project Model from three kinds of sources:- The Native, Classic, and Archive artifacts Comet manages;
- The project structure, manifest, and configuration that can be identified deterministically;
- The Markdown documents you specify through
knowledge.local.include.
include when needed. Per-file and total corpus sizes are limited by knowledge.local.max_file_mb and max_total_mb (defaults 1 MB and 32 MB); files over the limit stay out of the corpus and produce a diagnostic. You can also adjust both limits in the Dashboard’s Project Knowledge settings.
Distill project policies from execution results
While the Agent executes tasks, the Project Policy Learner processes completed events:- Review conclusions that were accepted and acted on;
- Faults whose root cause was confirmed, fixed, and re-verified successfully;
- Verifications that succeeded and the real commands behind them;
- The final decisions, stable patterns, operation flows, and deprecations in change archives;
- The success, ignore, correction, or failure results of Project Knowledge in later tasks.
trial and is promoted after successful use in later tasks. Source refresh checks validity; it does not promote untried experience to confirmed knowledge.
Source-validity checks
Every record keeps its project identity, source path, applicable scope, source version, and verification information. Before content enters a task, Comet runs these checks:- When the source content is unchanged, the record keeps participating in retrieval.
- When the source changed, the old conclusion stops being used as current content.
- When the source is deleted or a selector stops applying, the record enters
superseded. - When a verification command disappears, the previous
enforcedstate stops being valid. - New evidence forms a new version and keeps its replacement relationship with the old version.
Task recall and provision
Context Director filters candidates by the current project, path, task, operation, phase, type, and state, then ranks them using Markdown full-text search, bounded exact search, project relationships, source status, and application results. Without a file path, the Agent can discover relevant knowledge and expand its scope, sources, and verification methods. Explicit scope mismatches are still excluded. A few keyproven or enforced Project Policies can be provided in full. Project Model entries, trial policies, longer procedures, and evidence usually enter the Context Manifest first. The Manifest carries only summaries, application reasons, and stable IDs, and the Agent expands the full content, source, and verification method as needed.
The success, ignore, override, correction, or failure results after the Agent uses the content feed back into later ranking and the lifecycle.
Management entry
The Dashboard’s Project Knowledge page separates Project Models from Project Policies and shows each record’s applicable scope, source, verification method, state,whyApplied, recent application results, and full history; project memories are shown in a separate Project Memory tab.
The CLI reads and writes the same state:
knowledge.local.include; that the record’s project, path, operation, phase, and lifecycle match the task; that the source version is still valid; that the Query returns relevant candidates; and that the whyApplied and application history in the Context Manifest match expectations.
Product boundaries
Project Knowledge serves the Agent’s understanding of the project within these boundaries:- The current source code, configuration, tests, and Runtime state always take priority;
- The platform keeps using the original Rule files and loading mechanism;
- Personal Memory can become team knowledge only through an explicit sharing action that removes personal information and re-checks sources;
- linter, compiler, test, build, and CI stay maintained by the project’s existing tools;
- Project Knowledge grants no commit, push, delete, or publish permissions;
- Disabling the plugin stops learning, querying, policy verification, and Remote requests; disable it in the Dashboard plugin center, and it is enabled by default after initialization.